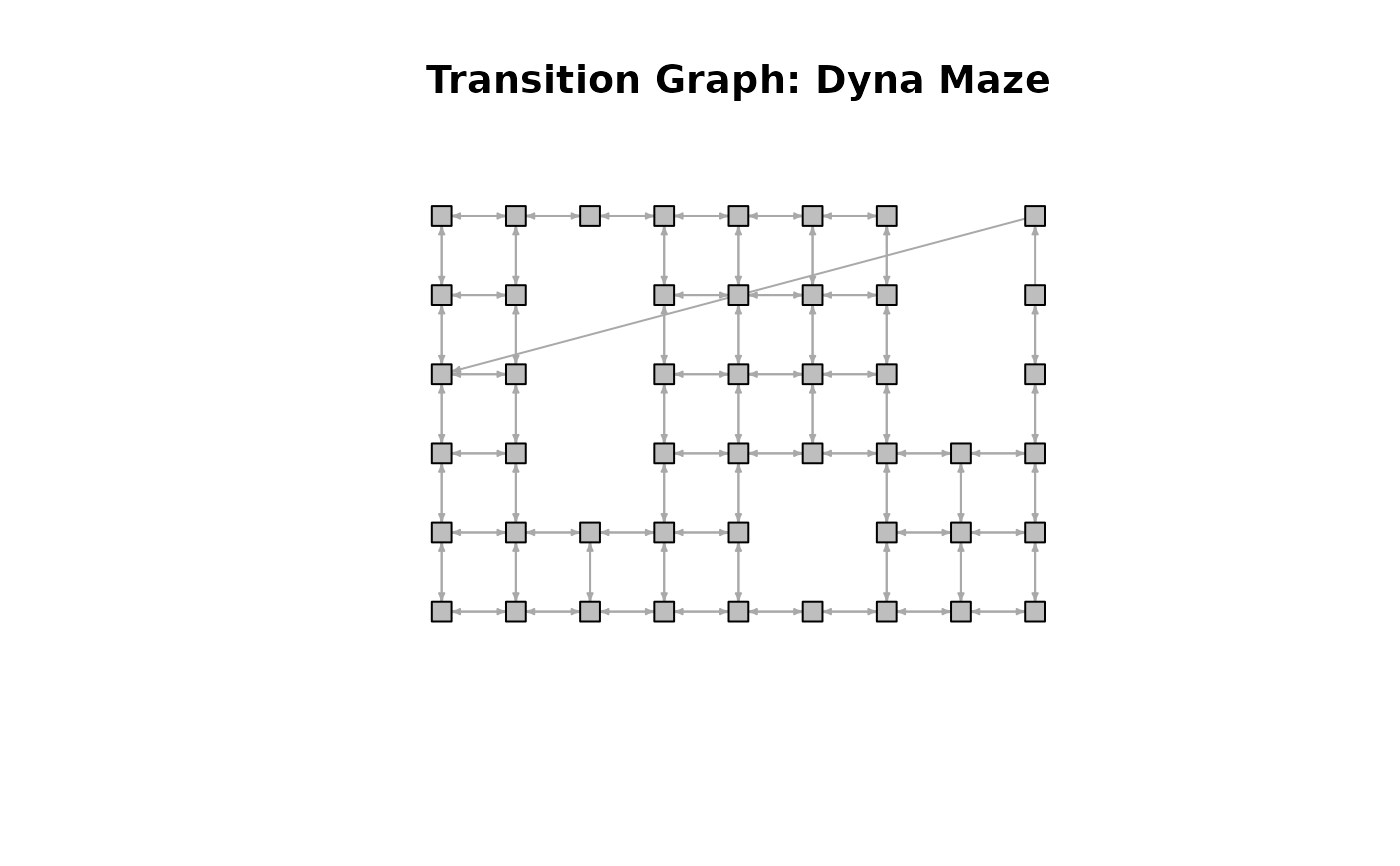
The Dyna Maze from Chapter 8 of the textbook "Reinforcement Learning: An Introduction."
Format
An object of class MDP.
References
Richard S. Sutton and Andrew G. Barto (2018). Reinforcement Learning: An Introduction Second Edition, MIT Press, Cambridge, MA.
See also
Other MDP_examples:
Cliff_walking,
MDP(),
Maze,
Windy_gridworld
Other gridworld:
Cliff_walking,
Maze,
Windy_gridworld,
gridworld
Examples
data(DynaMaze)

DynaMaze
#> MDP, list - Dyna Maze
#>   Discount factor: 0.95
#>   Horizon: Inf epochs
#>   Size: 47 states / 5 actions
#>   Start: s(3,1)
#>
#>   List components: ‘name’, ‘discount’, ‘horizon’, ‘states’, ‘actions’,
#>     ‘transition_prob’, ‘reward’, ‘info’, ‘start’

gridworld_matrix(DynaMaze)
#>      [,1]     [,2]     [,3]     [,4]     [,5]     [,6]     [,7]     [,8]
#> [1,] "s(1,1)" "s(1,2)" "s(1,3)" "s(1,4)" "s(1,5)" "s(1,6)" "s(1,7)" NA
#> [2,] "s(2,1)" "s(2,2)" NA       "s(2,4)" "s(2,5)" "s(2,6)" "s(2,7)" NA
#> [3,] "s(3,1)" "s(3,2)" NA       "s(3,4)" "s(3,5)" "s(3,6)" "s(3,7)" NA
#> [4,] "s(4,1)" "s(4,2)" NA       "s(4,4)" "s(4,5)" "s(4,6)" "s(4,7)" "s(4,8)"
#> [5,] "s(5,1)" "s(5,2)" "s(5,3)" "s(5,4)" "s(5,5)" NA       "s(5,7)" "s(5,8)"
#> [6,] "s(6,1)" "s(6,2)" "s(6,3)" "s(6,4)" "s(6,5)" "s(6,6)" "s(6,7)" "s(6,8)"
#>      [,9]
#> [1,] "s(1,9)"
#> [2,] "s(2,9)"
#> [3,] "s(3,9)"
#> [4,] "s(4,9)"
#> [5,] "s(5,9)"
#> [6,] "s(6,9)"
gridworld_matrix(DynaMaze, what = "labels")
#>      [,1]    [,2] [,3] [,4] [,5] [,6] [,7] [,8] [,9]
#> [1,] ""      ""   ""   ""   ""   ""   ""   "X"  "Goal"
#> [2,] ""      ""   "X"  ""   ""   ""   ""   "X"  ""
#> [3,] "Start" ""   "X"  ""   ""   ""   ""   "X"  ""
#> [4,] ""      ""   "X"  ""   ""   ""   ""   ""   ""
#> [5,] ""      ""   ""   ""   ""   "X"  ""   ""   ""
#> [6,] ""      ""   ""   ""   ""   ""   ""   ""   ""

gridworld_plot_transition_graph(DynaMaze)