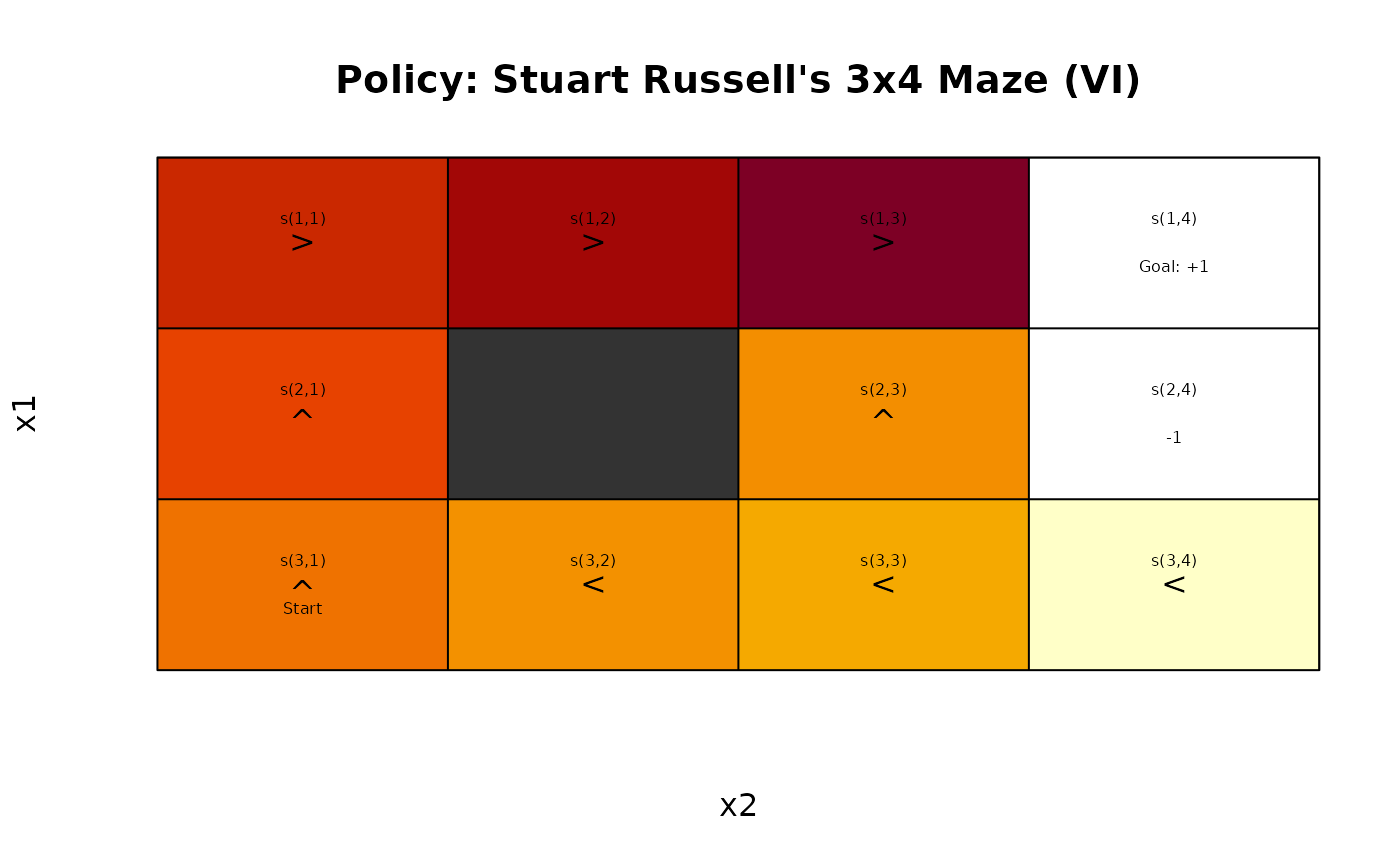
The 4x3 maze is described in Chapter 17 of the textbook "Artificial Intelligence: A Modern Approach" (AIMA).
Format
An object of class MDP.
Details
The simple maze has the following layout:
    1234           Transition model:
   ######             .8 (action direction)
  1#   +#              ^
  2# # -#              |
  3#S   #         .1 <-|-> .1
   ######
We represent the maze states as a gridworld matrix with 3 rows and
4 columns. The states are labeled s(row, col) representing the position in
the matrix.
The # (state s(2,2)) in the middle of the maze is an obstruction and not reachable.
Rewards are associated with transitions. The default reward (penalty) is -0.04.
The start state marked with S is s(3,1).
Transitioning to + (state s(1,4)) gives a reward of +1.0,
transitioning to - (state s_(2,4))
has a reward of -1.0. Both these states are absorbing
(i.e., terminal) states.
Actions are movements (up, right, down, left). The actions are
unreliable with a .8 chance
to move in the correct direction and a 0.1 chance to instead to move in a
perpendicular direction leading to a stochastic transition model.
Note that the problem has reachable terminal states which leads to a proper policy
(that is guaranteed to reach a terminal state). This means that the solution also
converges without discounting (discount = 1).
References
Russell,9 S. J. and Norvig, P. (2020). Artificial Intelligence: A modern approach. 4rd ed.
See also
Other MDP_examples:
Cliff_walking,
DynaMaze,
MDP(),
Windy_gridworld
Other gridworld:
Cliff_walking,
DynaMaze,
Windy_gridworld,
gridworld
Examples
# The problem can be loaded using data(Maze).
# Here is the complete problem definition.
# We first look at the state layout
gw_matrix(gw_init(dim = c(3, 4)))
#> [,1] [,2] [,3] [,4]
#> [1,] "s(1,1)" "s(1,2)" "s(1,3)" "s(1,4)"
#> [2,] "s(2,1)" "s(2,2)" "s(2,3)" "s(2,4)"
#> [3,] "s(3,1)" "s(3,2)" "s(3,3)" "s(3,4)"
# the wall at s(2,2) is unreachable
gw <- gw_init(dim = c(3, 4),
start = "s(3,1)",
goal = "s(1,4)",
absorbing_states = c("s(1,4)", "s(2,4)"),
blocked_states = "s(2,2)",
state_labels = list(
"s(3,1)" = "Start",
"s(2,4)" = "-1",
"s(1,4)" = "Goal: +1")
)
gw_matrix(gw)
#> [,1] [,2] [,3] [,4]
#> [1,] "s(1,1)" "s(1,2)" "s(1,3)" "s(1,4)"
#> [2,] "s(2,1)" NA "s(2,3)" "s(2,4)"
#> [3,] "s(3,1)" "s(3,2)" "s(3,3)" "s(3,4)"
gw_matrix(gw, what = "index")
#> [,1] [,2] [,3] [,4]
#> [1,] 1 4 6 9
#> [2,] 2 NA 7 10
#> [3,] 3 5 8 11
gw_matrix(gw, what = "labels")
#> [,1] [,2] [,3] [,4]
#> [1,] "" "" "" "Goal: +1"
#> [2,] "" "X" "" "-1"
#> [3,] "Start" "" "" ""
# gw_init has created the following information
str(gw)
#> List of 7
#> $ states : chr [1:11] "s(1,1)" "s(2,1)" "s(3,1)" "s(1,2)" ...
#> $ actions : chr [1:4] "up" "right" "down" "left"
#> $ transition_model:function (model, action, start.state)
#> $ reward :'data.frame': 1 obs. of 4 variables:
#> ..$ action : logi NA
#> ..$ start.state: logi NA
#> ..$ end.state : logi NA
#> ..$ value : num 0
#> $ start : chr "s(3,1)"
#> $ info :List of 6
#> ..$ gridworld : logi TRUE
#> ..$ dim : num [1:2] 3 4
#> ..$ start : chr "s(3,1)"
#> ..$ goal : chr "s(1,4)"
#> ..$ state_labels :List of 3
#> .. ..$ s(3,1): chr "Start"
#> .. ..$ s(2,4): chr "-1"
#> .. ..$ s(1,4): chr "Goal: +1"
#> ..$ absorbing_states: chr [1:2] "s(1,4)" "s(2,4)"
#> $ absorbing_states: chr [1:2] "s(1,4)" "s(2,4)"
# the transition function is stochastic so we cannot use the standard
# gridworld function provided in gw$transition_model() and we
# have to replace it
P <- function(model, action, start.state) {
action <- match.arg(action, choices = A(model))
P <- structure(numeric(length(S(model))), names = S(model))
# absorbing states
if (start.state %in% model$info$absorbing_states) {
P[start.state] <- 1
return(P)
}
if (action %in% c("up", "down")) {
error_direction <- c("right", "left")
} else {
error_direction <- c("up", "down")
}
rc <- gw_s2rc(start.state)
delta <- list(
up = c(-1, 0),
down = c(+1, 0),
right = c(0, +1),
left = c(0, -1)
)
# there are 3 directions. For blocked directions, stay in place
# 1) action works .8
rc_new <- gw_rc2s(rc + delta[[action]])
if (rc_new %in% S(model))
P[rc_new] <- .8
else
P[start.state] <- .8
# 2) off to the right .1
rc_new <- gw_rc2s(rc + delta[[error_direction[1]]])
if (rc_new %in% S(model))
P[rc_new] <- .1
else
P[start.state] <- P[start.state] + .1
# 3) off to the left .1
rc_new <- gw_rc2s(rc + delta[[error_direction[2]]])
if (rc_new %in% S(model))
P[rc_new] <- .1
else
P[start.state] <- P[start.state] + .1
P
}
P(gw, "up", "s(3,1)")
#> s(1,1) s(2,1) s(3,1) s(1,2) s(3,2) s(1,3) s(2,3) s(3,3) s(1,4) s(2,4) s(3,4)
#> 0.0 0.8 0.1 0.0 0.1 0.0 0.0 0.0 0.0 0.0 0.0
R <- rbind(
R_( value = -0.04),
R_(end.state = "s(2,4)", value = -1 - 0.04),
R_(end.state = "s(1,4)", value = +1 - 0.04),
R_(start.state = "s(2,4)", value = 0),
R_(start.state = "s(1,4)", value = 0)
)
Maze <- MDP(
name = "Stuart Russell's 3x4 Maze",
discount = 1,
horizon = Inf,
states = gw$states,
actions = gw$actions,
start = "s(3,1)",
transition_model = P,
reward = R,
info = gw$info
)
Maze
#> MDPModel, MDP - Stuart Russell's 3x4 Maze
#> Discount factor: 1
#> Horizon: Inf epochs
#> Size: 4 actions / 11 states
#> Storage: transition prob as function / reward as data.frame. Total size: 28.5 Kb
#> Start: s(3,1)
#> Model list components: ‘name’, ‘discount’, ‘horizon’, ‘states’,
#> ‘actions’, ‘start’, ‘transition_model’, ‘reward’, ‘info’
str(Maze)
#> List of 9
#> $ name : chr "Stuart Russell's 3x4 Maze"
#> $ discount : num 1
#> $ horizon : num Inf
#> $ states : chr [1:11] "s(1,1)" "s(2,1)" "s(3,1)" "s(1,2)" ...
#> $ actions : chr [1:4] "up" "right" "down" "left"
#> $ start : chr "s(3,1)"
#> $ transition_model:function (model, action, start.state)
#> $ reward :'data.frame': 5 obs. of 4 variables:
#> ..$ action : chr [1:5] NA NA NA NA ...
#> ..$ start.state: chr [1:5] NA NA NA "s(2,4)" ...
#> ..$ end.state : chr [1:5] NA "s(2,4)" "s(1,4)" NA ...
#> ..$ value : num [1:5] -0.04 -1.04 0.96 0 0
#> $ info :List of 6
#> ..$ gridworld : logi TRUE
#> ..$ dim : num [1:2] 3 4
#> ..$ start : chr "s(3,1)"
#> ..$ goal : chr "s(1,4)"
#> ..$ state_labels :List of 3
#> .. ..$ s(3,1): chr "Start"
#> .. ..$ s(2,4): chr "-1"
#> .. ..$ s(1,4): chr "Goal: +1"
#> ..$ absorbing_states: chr [1:2] "s(1,4)" "s(2,4)"
#> - attr(*, "class")= chr [1:2] "MDPModel" "MDP"
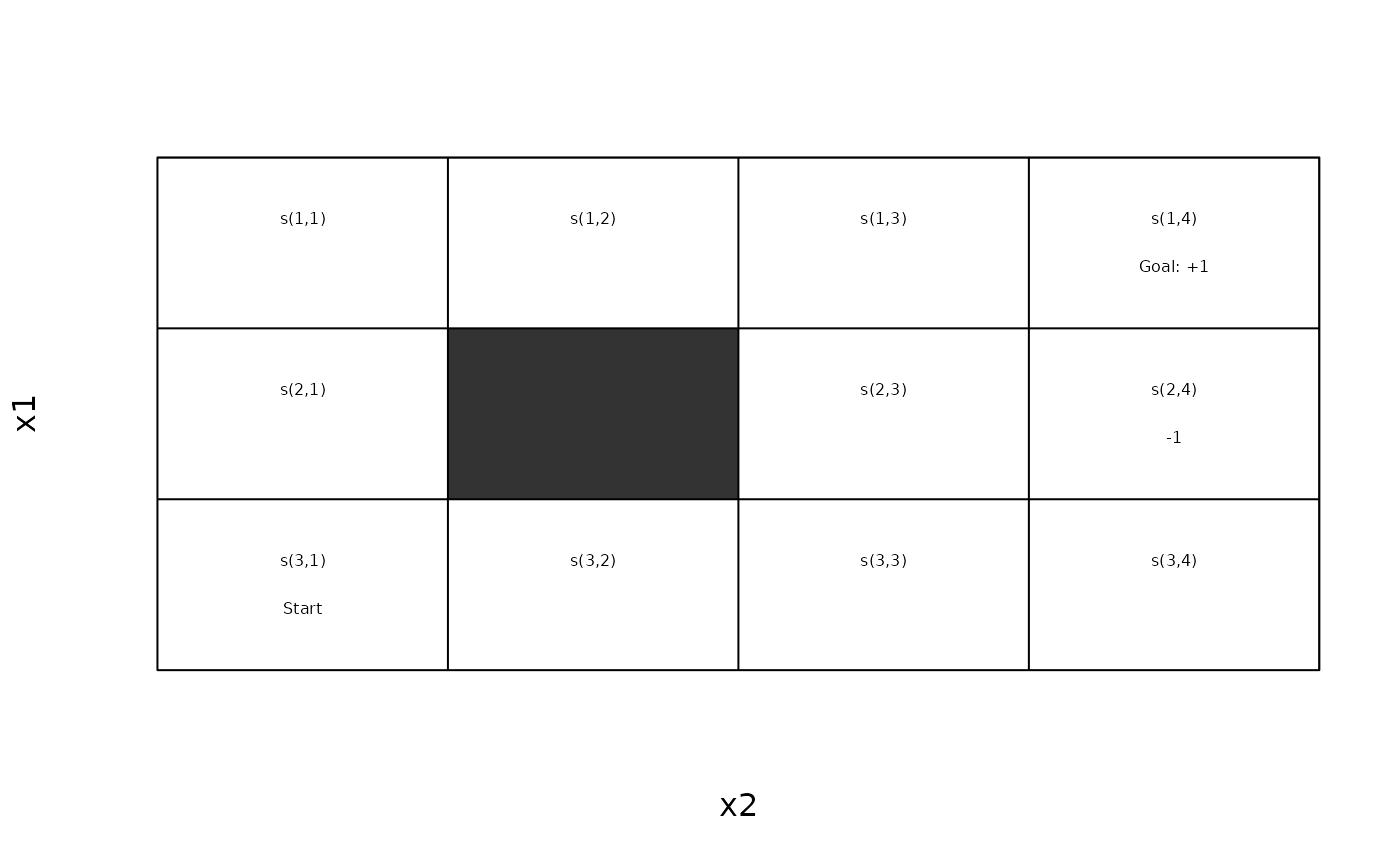
gw_matrix(Maze)
#> [,1] [,2] [,3] [,4]
#> [1,] "s(1,1)" "s(1,2)" "s(1,3)" "s(1,4)"
#> [2,] "s(2,1)" NA "s(2,3)" "s(2,4)"
#> [3,] "s(3,1)" "s(3,2)" "s(3,3)" "s(3,4)"
gw_matrix(Maze, what = "labels")
#> [,1] [,2] [,3] [,4]
#> [1,] "" "" "" "Goal: +1"
#> [2,] "" "X" "" "-1"
#> [3,] "Start" "" "" ""
gw_plot(Maze)
 # find absorbing (terminal) states
absorbing_states(Maze)
#> [1] "s(1,4)" "s(2,4)"
maze_solved <- solve_MDP(Maze)
policy(maze_solved)
#> state V action
#> 1 s(1,1) 0.8115564 right
#> 2 s(2,1) 0.7615521 up
#> 3 s(3,1) 0.7052527 up
#> 4 s(1,2) 0.8678082 right
#> 5 s(3,2) 0.6551492 left
#> 6 s(1,3) 0.9178082 right
#> 7 s(2,3) 0.6602740 up
#> 8 s(3,3) 0.6110843 left
#> 9 s(1,4) 0.0000000 right
#> 10 s(2,4) 0.0000000 up
#> 11 s(3,4) 0.3872455 left
gw_matrix(maze_solved, what = "values")
#> [,1] [,2] [,3] [,4]
#> [1,] 0.8115564 0.8678082 0.9178082 0.0000000
#> [2,] 0.7615521 NA 0.6602740 0.0000000
#> [3,] 0.7052527 0.6551492 0.6110843 0.3872455
gw_matrix(maze_solved, what = "actions")
#> [,1] [,2] [,3] [,4]
#> [1,] "right" "right" "right" "right"
#> [2,] "up" NA "up" "up"
#> [3,] "up" "left" "left" "left"
gw_plot(maze_solved)