Micro Clusterer. BICO maintains a tree which is inspired by the clustering tree of BIRCH. Each node in the tree represents a subset of these points. Instead of storing all points as individual objects, only the number of points, the sum and the squared sum of the subset's points are stored as key features of each subset. Points are inserted into exactly one node.
Arguments
- formula
NULLto use all features in the stream or a model formula of the form~ X1 + X2to specify the features used for clustering. Only.,+and-are currently supported in the formula.- k
number of centers.
- space
coreset size.
- p
number of random projections used for nearest neighbor search in first level.
- iterations
number of repetitions for the kmeans++ procedure in the offline component.
Details
In this implementation, the nearest neighbor search on the first level of
the tree is sped up by projecting all points to random 1-d subspaces. The
first estimation of the optimal clustering cost is computed in a buffer
phase at the beginning of the algorithm. This implementation interfaces the
original C++ implementation. For micro-clustering,
the algorithm computes the coreset of the stream. Reclustering is performed
by using the kmeans++ algorithm on the coreset.
References
Hendrik Fichtenberger, Marc Gille, Melanie Schmidt, Chris Schwiegelshohn, Christian Sohler: BICO: BIRCH Meets Coresets for k-Means Clustering. ESA 2013: 481-492.
See also
Other DSC_Micro:
DSC_BIRCH(),
DSC_DBSTREAM(),
DSC_DStream(),
DSC_Micro(),
DSC_Sample(),
DSC_Window(),
DSC_evoStream()
Author
R-Interface: Matthias Carnein (Matthias.Carnein@uni-muenster.de), Dennis Assenmacher. C-Implementation: Hendrik Fichtenberger, Marc Gille, Melanie Schmidt, Chris Schwiegelshohn, Christian Sohler.
Examples
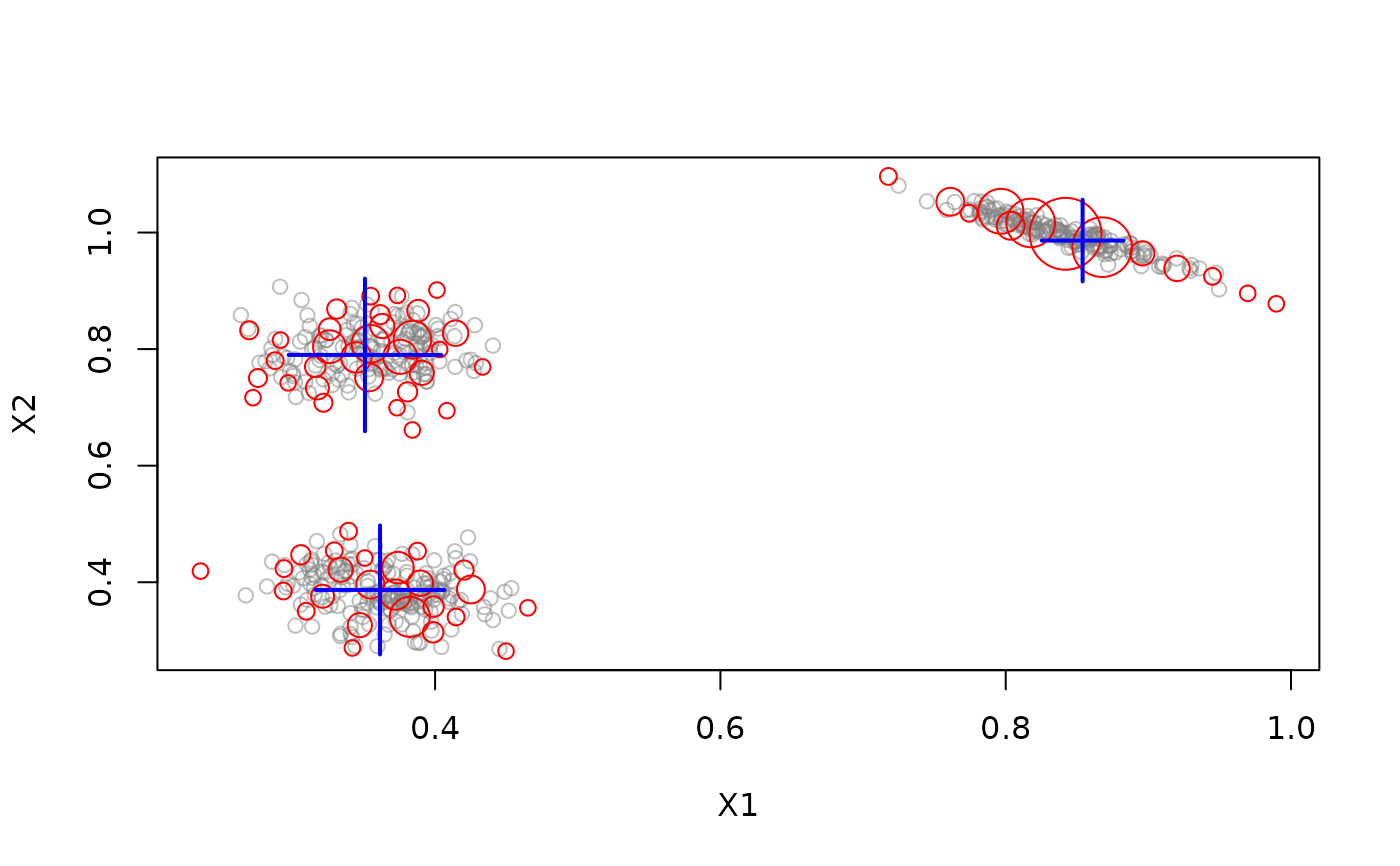
stream <- DSD_Gaussians(k = 3, d = 2)

BICO <- DSC_BICO(k = 3, p = 10, space = 100, iterations = 10)
update(BICO, stream, n = 500)

plot(BICO,stream)